
Real-Time Lip Sync, Adaptive Full-Duplex Dialogue, and Controllable TTS
Today's digest spans real-time lip sync in unconstrained scenes, three complementary takes on full-duplex spoken dialogue (adaptive turn-taking, synthetic training data, and backchannel control), physiology-aware head avatars, sign language avatars, and two new flow-based TTS frameworks.
Overview of ComplexSync. (a) Dual-stream joint training strategy designed to suppress spatial information leakage and ensure high-fidelity synthesis. (b) Distillation-based acceleration scheme that facilitates single-step denoising for real-time inference. (c) Relational alignment loss leveraging VFMs to enhance synchronization precision and robustness under unconstrained conditions. From Tsinghua University.
Today's papers push hard on two fronts: making avatars and lip sync work in the wild at real-time speeds, and taming the fine-grained dynamics of full-duplex spoken conversation — turn-taking, interruptions, and backchannels. On the synthesis side, two new flow-based TTS systems tackle prosody controllability and variable-length editing from fresh angles.
Talking Avatars & Lip Sync
From high-speed lip sync to biometric-aware head avatars and photorealistic sign language rendering — avatar research is reaching into new territory.
Real-time, high-fidelity lip sync in unconstrained video has been a persistent bottleneck. ComplexSync from Tsinghua University attacks this with a diffusion-based framework that clears 70 FPS while remaining robust to complex, in-the-wild scenes. The key engineering choices are a dual-stream joint training strategy that prevents spatial information leakage, distillation-based single-step denoising for inference acceleration, and a relational alignment loss anchored in Vision Foundation Models to handle scene-level complexity.
ComplexSync: High-Fidelity and Real-Time Lip Sync in Complex Scenarios
ComplexSync is a diffusion-based framework that generates high-fidelity lip movements synchronized with speech audio at real-time speeds (>70 FPS), with robust performance even in complex, unconstrained scenes. Unlike prior work, it combines dual-stream joint training to prevent spatial information leakage, distillation-based single-step denoising for acceleration, and a relational alignment loss grounded in Vision Foundation Models to improve robustness against scene complexity.
Abstract
Lip synchronization aims to generate visual lip dynamics that align precisely with speech audio. Despite the high generation quality of diffusion models, they often struggle in complex scenarios and suffer from prohibitive inference latency, limiting real-world deployment. We present ComplexSync, a unified diffusion-based framework that enables real-time, high-fidelity lip sync under complex conditions. First, we introduce a dual-stream joint training strategy to mitigate information leakage from reference frames while preserving natural dynamics. Second, we develop a distillation-based acceleration scheme for single-step denoising, achieving a throughput of over 70 FPS. Third, we propose a relational alignment loss that leverages structural priors from Vision Foundation Models (VFMs) to enhance robustness against complex scene factors. Furthermore, we present the first benchmark specifically designed for complex lip synchronization, comprising over 200 challenging video sequences and specialized metrics. Extensive experiments demonstrate that ComplexSync achieves state-of-the-art performance across both standard and complex scenarios while enabling real-time inference.
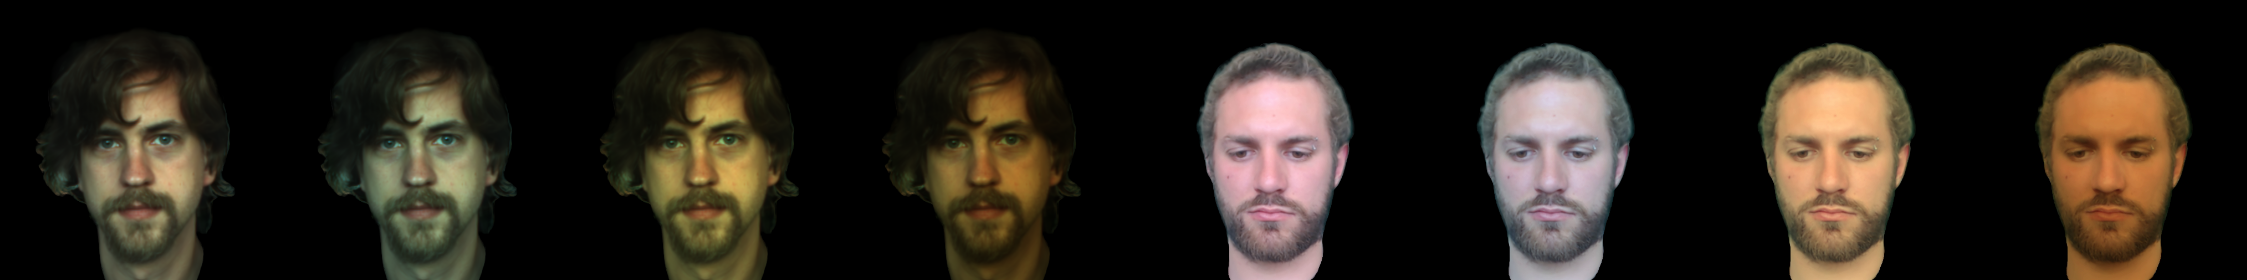
Gaussian head avatars are becoming standard, but the University of Oulu's Heartian pushes them into genuinely new territory by embedding cardiac-cycle physiology into the rendering pipeline. Per-frame skin albedo modulations are learned in sync with cardiac waveforms, and critically, the embedded remote photoplethysmography (rPPG) signals survive the rendering process and remain recoverable by standard algorithms — meaning these photorealistic avatars carry detectable biometric information.
$\unicode{x1F493}$Heartian: Physiology-Aware Relightable Gaussian Head Avatar
This work embeds cardiac-cycle-dependent physiological signals into relightable Gaussian head avatars by learning per-frame skin albedo modulations synchronized with cardiac waveforms. The key innovation is that the embedded remote photoplethysmography (rPPG) signals remain detectable by standard algorithms even after rendering, enabling photorealistic avatars that encode recoverable biometric information.
Abstract
Gaussian head avatars typically model intrinsic facial appearance as temporally static, omitting subtle cardiac-induced skin-color variation. We propose $\unicode{x1F493}$Heartian, a physiology-aware modulation framework that learns cardiac-cycle-dependent per-frame albedo modulation of facial skin-region Gaussians within a relightable head avatar to encode remote photoplethysmography (rPPG) signals. Using synchronized contact PPG supervision, $\unicode{x1F493}$Heartian models the prescribed cardiac waveform as the sum of two Gaussian functions and learns per-frame spatial residuals via a lightweight MLP. Across 152 stationary recordings from UBFC-rPPG, PURE, and MMPD, attribute-space recovery of the supplied signal achieves a pooled recording-level heart-rate MAE of 0.29 bpm and MAPE of 0.38%. The signals remain detectable after rendering by benchmark rPPG methods, with the best tested configuration - a motion-augmented TS-CAN decoder pretrained on UBFC-rPPG - recovering heart rate from the rendered MMPD avatars at 0.97 bpm MAE and 1.21% MAPE. Meanwhile, $\unicode{x1F493}$Heartian maintains reconstruction quality comparable to the baseline, with negligible average PSNR degradation of 0.005 dB. Overall, our work embeds recoverable rPPG signals as controllable material attributes to subject-specific Gaussian head avatars while retaining the reconstruction quality.
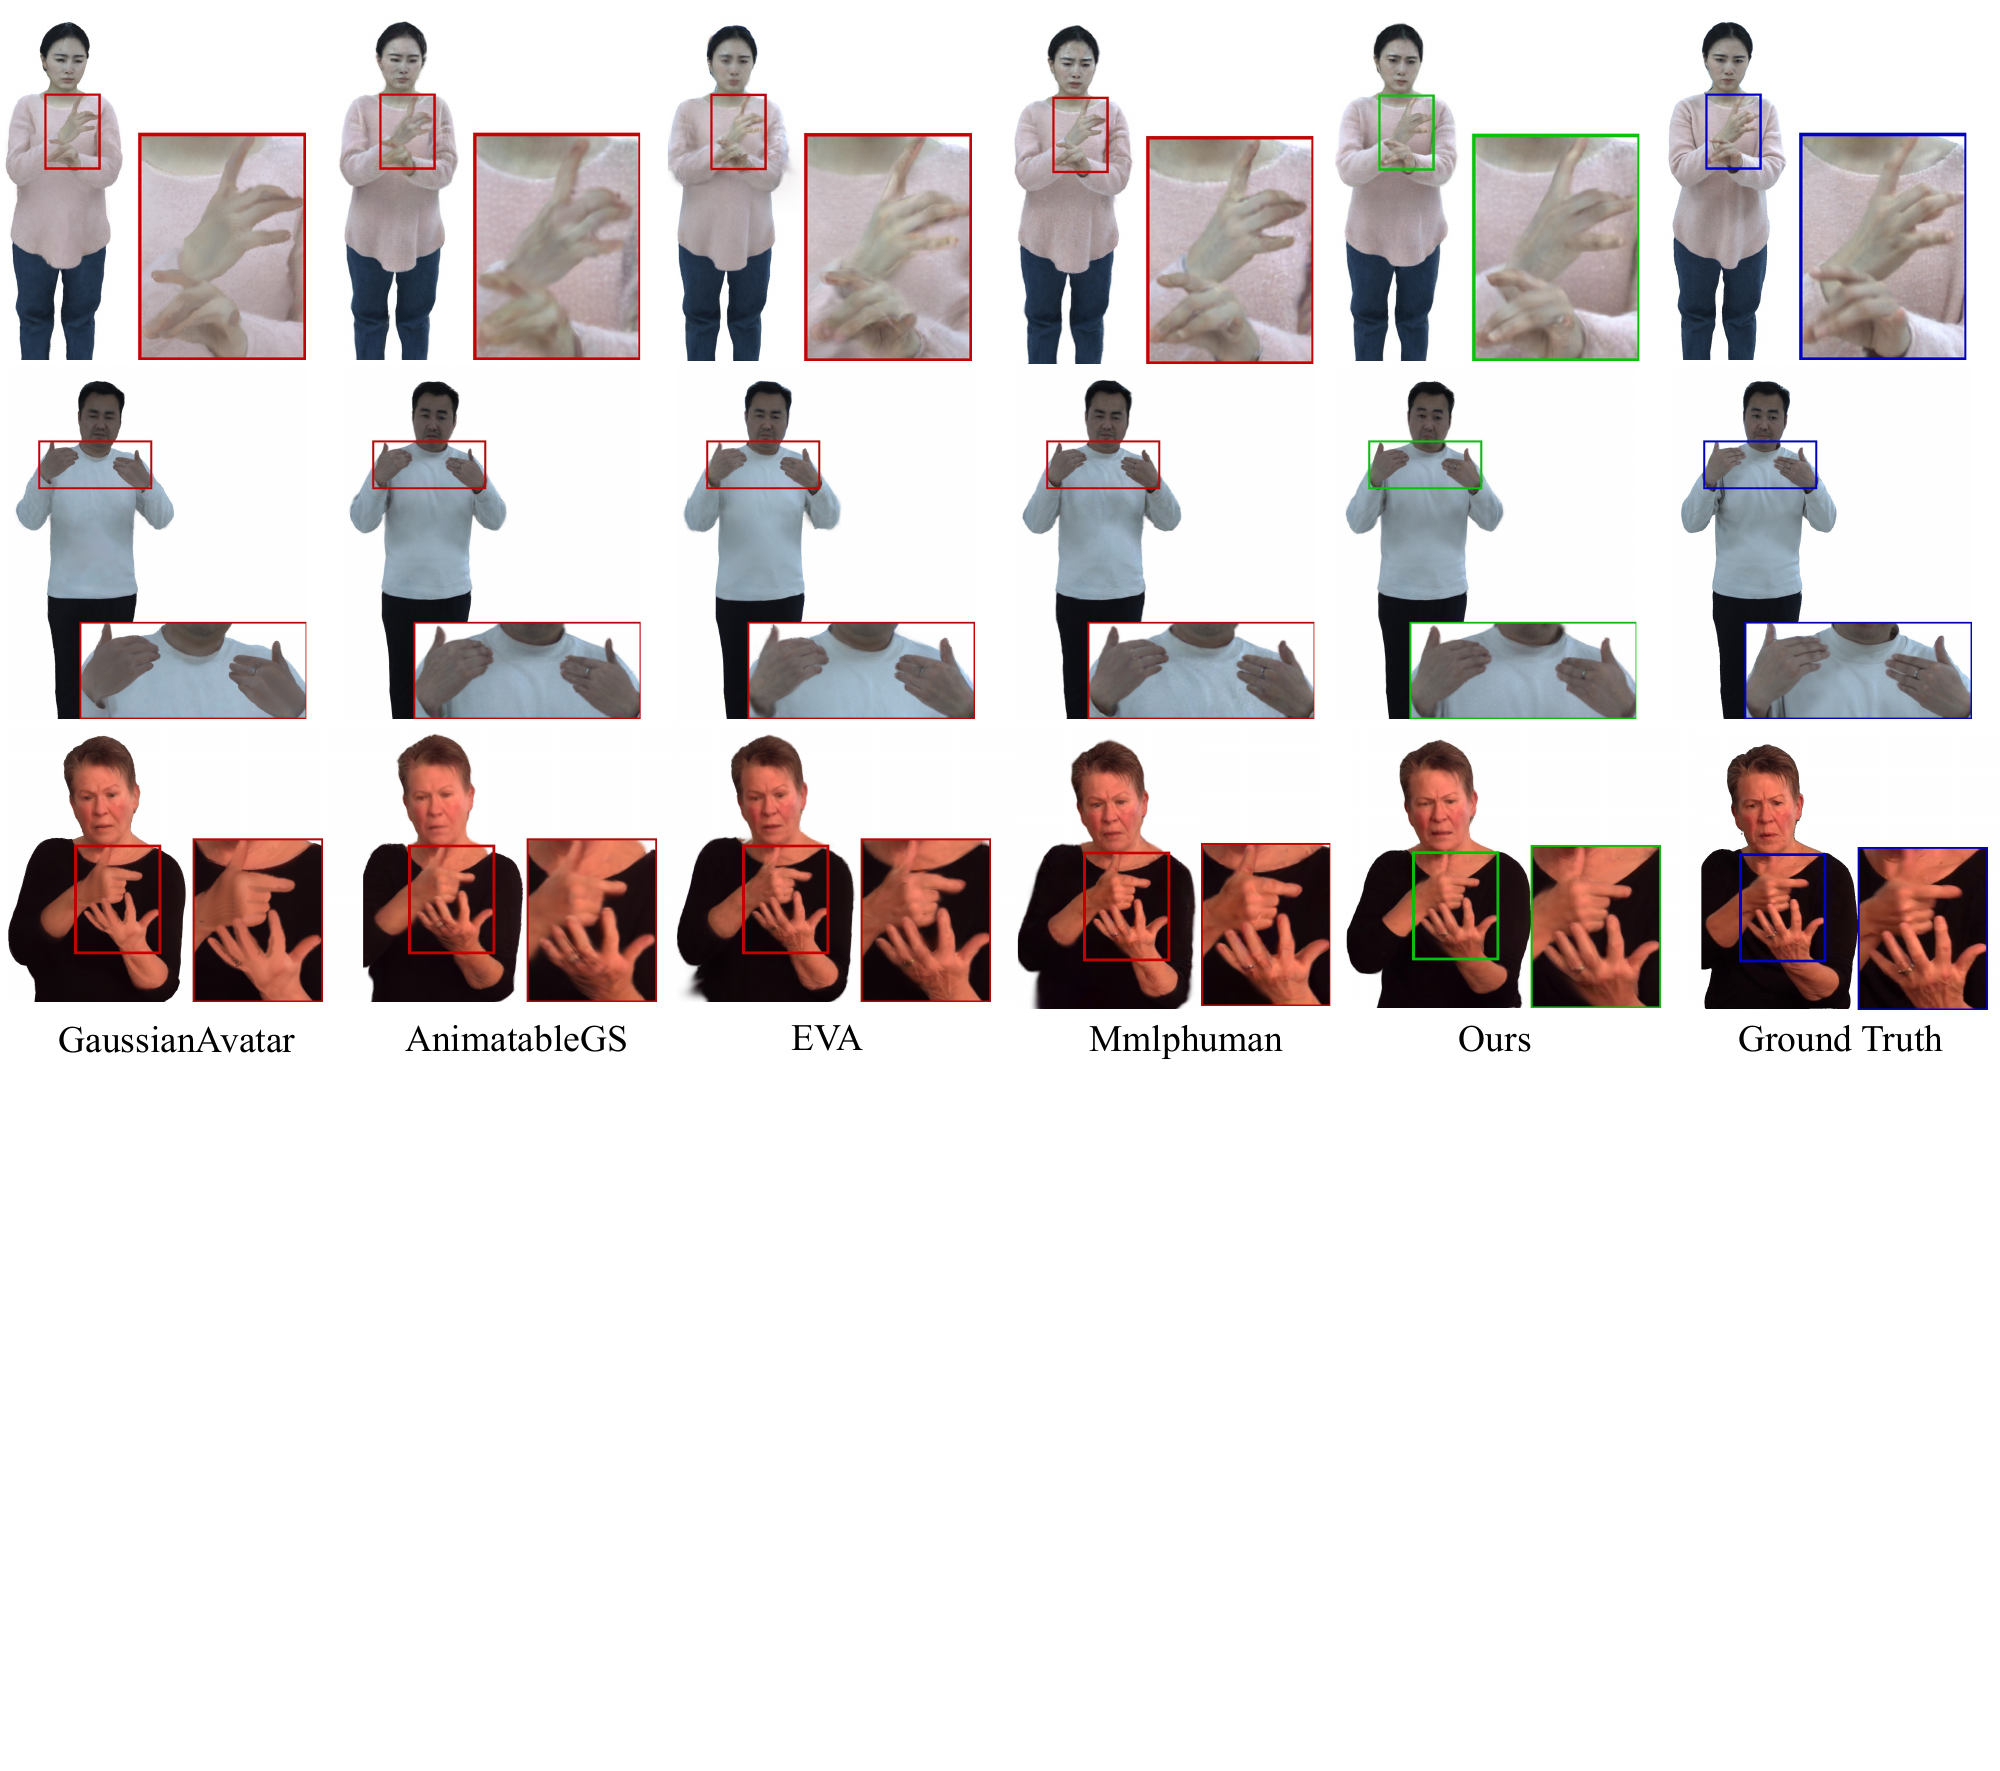
Sign language is a visual-gestural language that poses uniquely hard reconstruction challenges: hands, face, and body must all be captured with high fidelity. PHOSA from USTC introduces MVSign, the first multi-view Chinese Sign Language dataset co-designed with Deaf experts, and builds photorealistic 3D sign avatars on top of it using a decoupled representation that separates body, head, and hand components with motion-aware sampling. The system generalizes well to in-the-wild monocular video — a critical requirement for practical deployment.
PHOSA: Photorealistic 3D Sign Avatar Modeling and Benchmark
This work develops photorealistic 3D avatars specifically for sign language communication, introducing MVSign, the first multi-view Chinese sign language dataset co-designed with Deaf experts. The key innovation is a decoupled representation isolating body, head, and hand components with motion-aware sampling to capture the complex gestures and facial expressions critical for Deaf communication, achieving high-fidelity results that generalize well to in-the-wild monocular videos.
Abstract
In this work, we focus on photorealistic sign avatar modeling, which is crucial for effective communication with the Deaf community and is characterized by complex hand gestures and nuanced facial expressions. To this end, we introduce MVSign, the first multi-view Chinese sign language dataset co-designed with Deaf experts, featuring diverse gestures and rich annotations. For precise SMPL-X annotation, we develop a hybrid fitting pipeline that produces accurate body, hand, and facial parameters and can also be applied to the monocular setting. Building on MVSign, we propose a decoupled sign avatar representation that isolates body, head, and hand components to capture complex articulations, together with a motion-aware sampling strategy to handle motion blur and balance gesture diversity. Extensive experiments demonstrate that our method achieves high-fidelity visual results on MVSign, particularly in detailed hand and facial regions, and generalizes well to in-the-wild monocular sign language videos. Project page: https://naaapi.github.io/PHOSA.
SpeechLLMs, Full-Duplex & Voice Agents
Three papers this week converge on the same hard problem: making spoken dialogue systems that can listen and speak simultaneously, with human-like floor management.
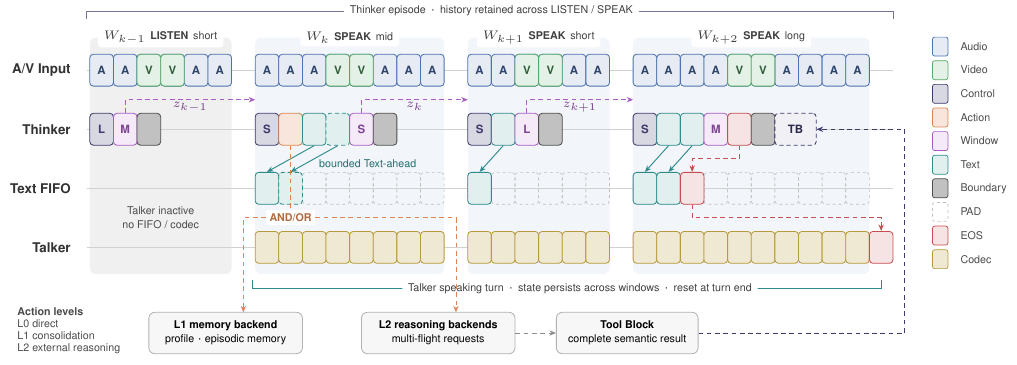
Full-duplex spoken dialogue models have mostly operated with fixed, static window sizes for listening and speaking. AdaptDuplex from Alibaba breaks that constraint by introducing dynamic window duration prediction and cognitive consolidation, enabling sub-second latency with genuinely adaptive turn-taking. A token-level protocol using explicit behavioral decision tokens allows training-free runtime control via logits bias — a practical handle for deployment-time tuning.
AdaptDuplex: from static to adaptive full-duplex spoken dialogue
AdaptDuplex upgrades full-duplex spoken dialogue from static to adaptive operation, enabling simultaneous listening and speaking at sub-second latency with dynamic window duration prediction and cognitive consolidation. It co-designs a token-level protocol with explicit behavioral decision tokens that support training-free runtime control via logits bias, achieving adaptive turn-taking and timing under real conversational demands.
Abstract
Full-duplex spoken dialogue requires simultaneous listening and speaking at sub-second latency, under conversational timing and cognitive demands that change moment to moment. Yet current models mostly impose static operating points, lacking a systematic mechanism for adaptive decisions. We present AdaptDuplex, which upgrades Qwen3-Omni with such a mechanism, co-designed across three layers. A compact token-level protocol represents every window as a canonical sequence, trains dual-stream alignment through a bounded text lead over speech, and exposes every behavioral decision as an explicit token for training-free runtime control via logits bias. Adaptive mechanisms dynamically predict among discrete window durations and augment direct response as needed with non-blocking cognitive consolidation and multi-flight external reasoning. A progressive pipeline introduces these behaviors through a three-stage Thinker curriculum, then Talker-only and joint SFT, with GRPO as a further increment. On Full-Duplex-Bench v1 and v1.5, AdaptDuplex outperforms DuplexOmni and MiniCPM-o 4.5 on the majority of comparable turn-taking, overlap-behavior, and timing metrics, with gains in both interaction decisions and response timing. On the human-recorded HumDial-FDBench, it attains the highest Final score (72.9) of the compared duplex models.
Training full-duplex models well requires data that captures the full range of overlapping speech, interruptions, and back-and-forth timing — data that is scarce in the wild. Kyutai's synthesis harness sidesteps this by having an LLM author relational dialogue events (without predicting absolute timestamps), then rendering and aligning them to produce precisely-controlled conversational phenomena. The resulting intent-labeled synthetic data provides learnable supervision that measurably improves floor-management in downstream full-duplex models.
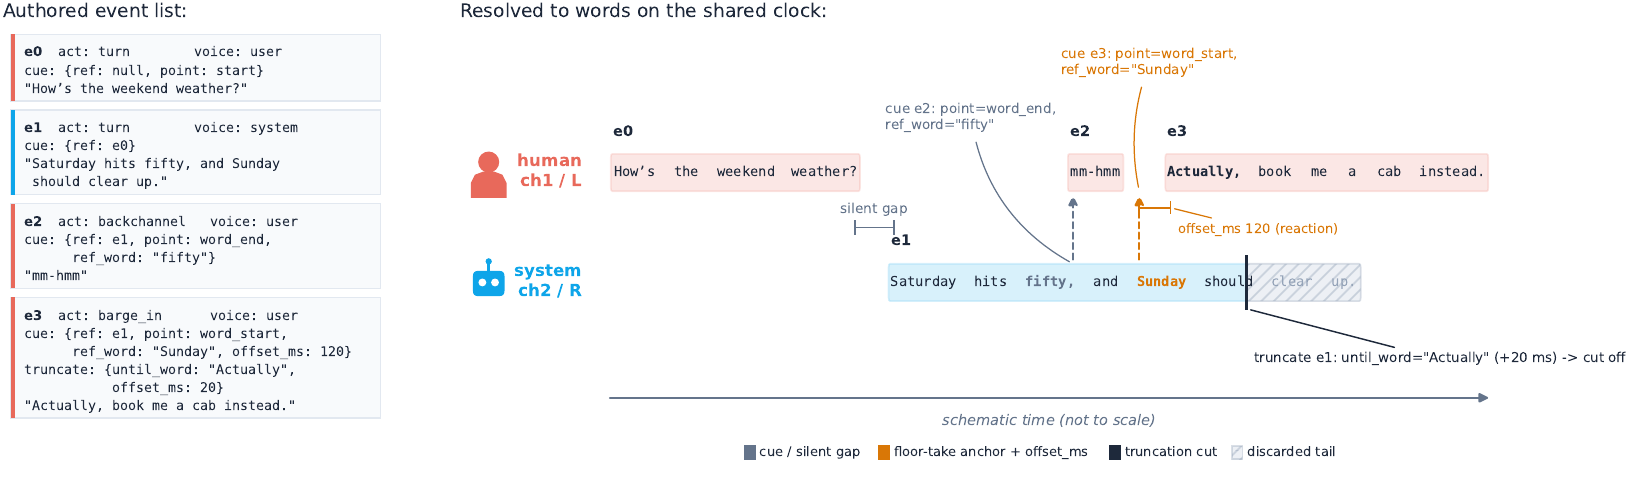
A Harness for Synthesizing Diverse Naturalistic Full-Duplex Conversations
This work presents a pipeline for synthesizing intent-labeled full-duplex conversational speech where an LLM authors relational dialogue events without predicting absolute timestamps, then renders and aligns them to create precisely-controlled overlaps, interruptions, and turn-taking phenomena. The approach uniquely bridges natural conversation and controlled synthesis, providing learnable supervision that significantly improves full-duplex models' floor-management capabilities.
Abstract
Full-duplex dialogue systems, which listen while speaking, must distinguish a completed turn from a pause within a turn and an interruption that requests a turn from a brief acknowledgment or speech addressed to a third party. Yet existing conversational corpora provide limited control over these events and limited labels for their intent. We present a pipeline for synthesizing intent-labeled, two-channel conversational speech from relational event lists. An LLM authors each event's speaker, text, conversational act, and attachment to an earlier event without predicting absolute timestamps. Events are synthesized independently, aligned with their source text, and placed on a shared clock, so turn-taking landmarks are measured from the rendered signal while silence durations are specified or sampled from turn-taking distributions. The pipeline covers 42 phenomena across eight families in English and Mandarin, derives frame-level system actions from authored intent, and promotes diversity using small, diverse sets of prior examples and batch prompts that request alternatives with self-reported probabilities. Ablations show gains in each targeted diversity dimension. On a four-action label space for taking, holding, releasing, and not holding the conversational floor, a semantic voice-activity detector using only current and past audio reaches start-speaking and start-listening F1 scores of 0.819 and 0.802. When generating its own responses, the full-duplex speech model Moshi takes 0.85 of the reference turns after fine-tuning on the generated corpus, compared with 0.44 before fine-tuning. Its frame-level precision for predicting system-floor occupancy rises from 0.46 to 0.88. With reference context at each step, its frame-level floor F1 rises from 0.893 to 0.962. These results show that controlled synthesis can provide learnable and transferable supervision for full-duplex turn management.
Backchannels — the "uh-huh," "mm," and "right" acknowledgements listeners produce — are a crucial signal of engagement, yet most dialogue systems ignore them entirely. The University of Edinburgh's paper introduces a lightweight backchannel head that plugs into existing full-duplex models, predicting backchannel timing from the model's own hidden states and triggering production via force-decoding at tunable thresholds. Evaluated across 1B–7B parameter models, the approach reaches human-level naturalness and timing.
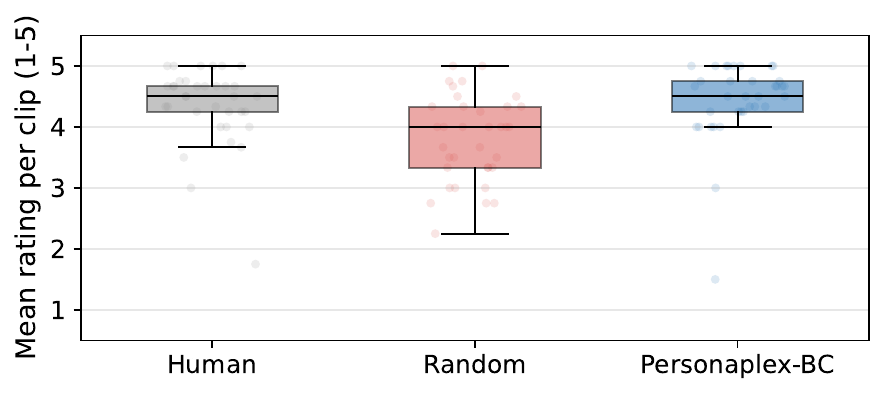
Controlling Backchannels in Streamable Full-duplex Models
This paper introduces a lightweight backchannel head for full-duplex conversational models that predicts when brief acknowledgements like "uh-huh" should occur, using the model's own hidden states and force-decoding at tunable thresholds. The approach achieves human-level backchannel naturalness and timing on models ranging from 1B to 7B parameters, enabling more naturally interactive dialogue systems.
Abstract
Backchannels, brief acknowledgements like "uh-huh" produced while the other party may still be talking, are central to natural conversation, but full-duplex spoken dialogue models rarely model them explicitly. We introduce a lightweight backchannel head that predicts, from a full-duplex model's own hidden states, when a backchannel should begin. Once this probability crosses a tunable threshold, a backchannel is force-decoded. Attached to both a 7B (PersonaPlex) and a 1B (F-Actor) model, it generalizes across scale. Probing confirms the hidden states anticipate real human timing, and generation evaluation shows more frequent, better-timed backchannels. Human raters judge the resulting backchannels on par with real ones.
TTS & Voice Synthesis
Two flow-based TTS systems tackle the same core challenge — modeling prosodic variation — from complementary directions.
Non-autoregressive TTS models have traditionally struggled to handle variable output lengths during zero-shot generation. EditVoice from Alibaba DAMO Academy introduces the first variable-length non-autoregressive zero-shot TTS model, using Edit Flows to control speech content and sequence length simultaneously through insertions, deletions, and substitutions. A unified speech-infilling training objective merges TTS and speech editing into a single model, and Complementary Prompt Sampling enables flexible prompt placement and training-free post-generation refinement.
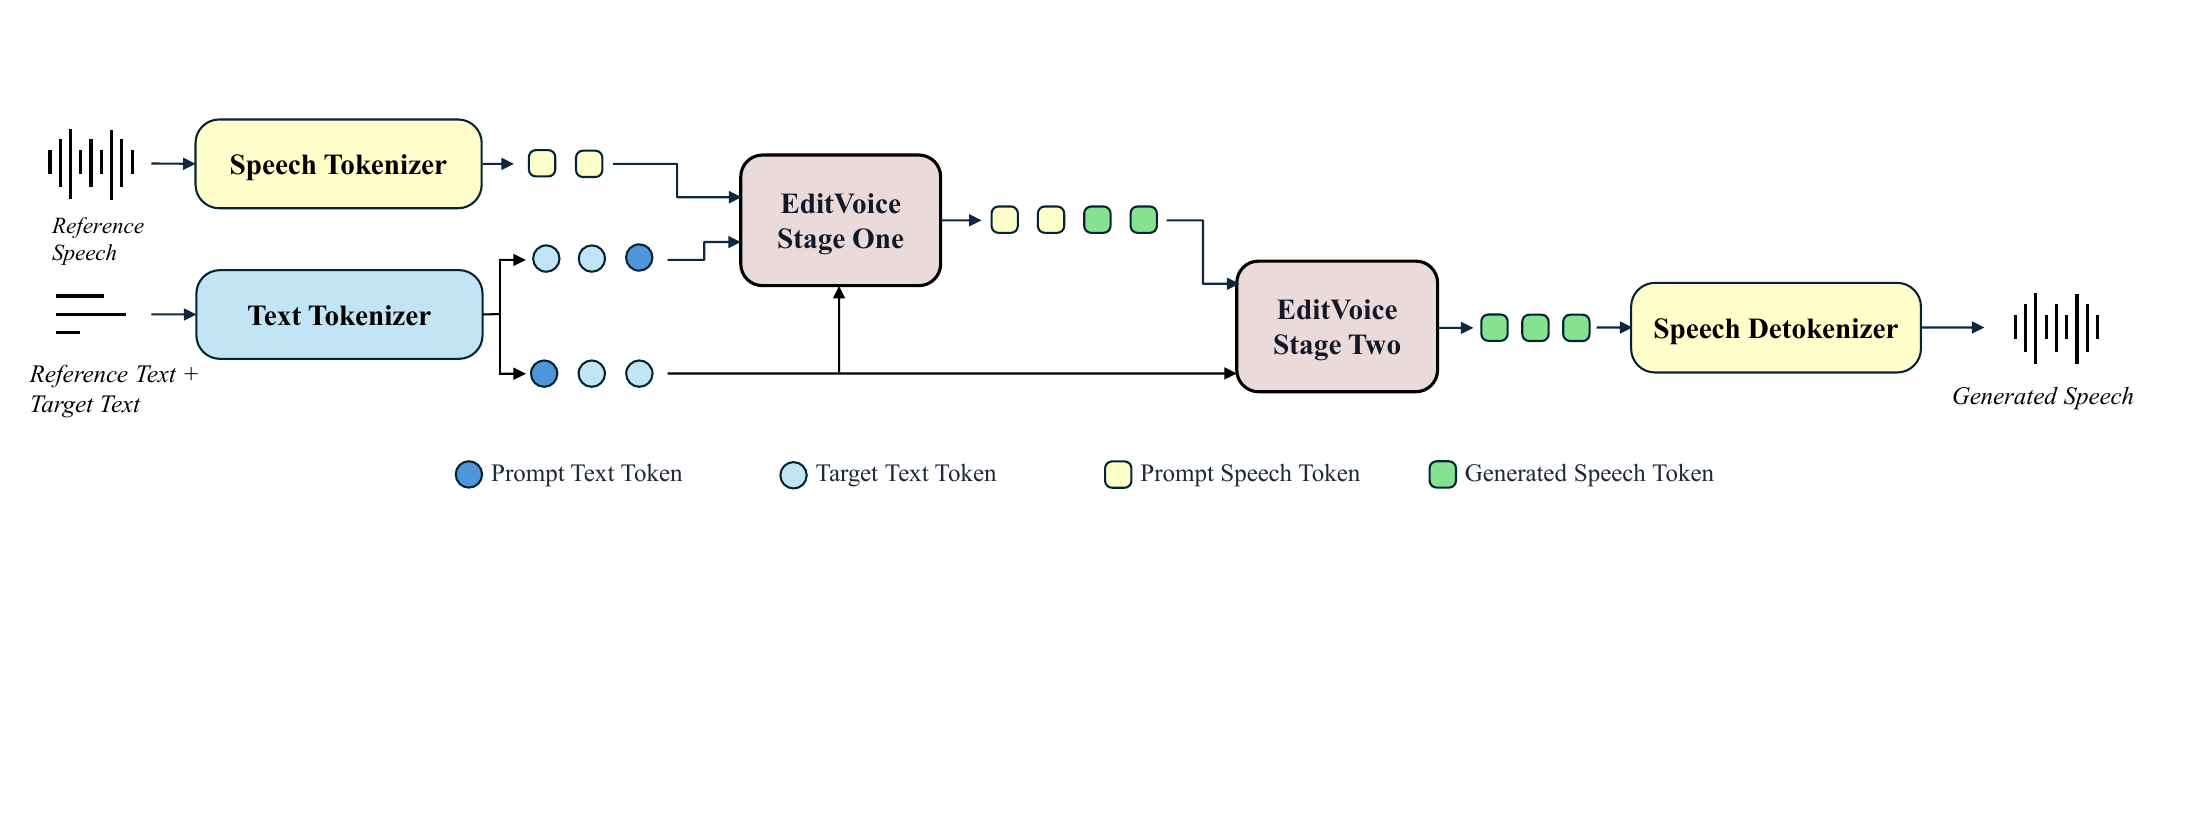
EditVoice: Variable-Length Non-Autoregressive Zero-Shot TTS and Speech Editing with Edit Flows
EditVoice introduces the first variable-length non-autoregressive zero-shot TTS model, using Edit Flows to dynamically control both speech content and sequence length through insertions, deletions, and substitutions. By unifying TTS and speech editing through speech-infilling training and proposing Complementary Prompt Sampling, the model achieves competitive zero-shot performance while enabling flexible prompt placement and training-free post-generation refinement.
Abstract
Recent non-autoregressive (NAR) zero-shot text-to-speech (TTS) models generate in parallel but typically require the target sequence length to be specified before generation. We introduce EditVoice, to our knowledge the first variable-length NAR zero-shot TTS model, which uses Edit Flows to jointly update speech content and sequence length through insertions, deletions, and substitutions. EditVoice adopts speech-infilling training, which unifies zero-shot TTS and text-based speech editing and allows both prefix and suffix speech prompt placements at inference. We introduce Complementary Prompt Sampling (CPS) to leverage the complementary Edit Flow predictions induced by the two prompt placements. We further find that EditVoice can edit source and model-generated speech beyond its training sources. We use this generalization for end-to-end editing and training-free post-generation refinement. With the Edit Flow model trained on 10K h of GigaSpeech, EditVoice demonstrates competitive zero-shot TTS performance on Seed-TTS Eval EN and LibriSpeech-PC and speech editing performance on RealEdit.
Prosody in TTS is notoriously hard to control because most flow-matching frameworks marginalize over the latent variation between utterances rather than modeling it explicitly. ReaFlow-TTS from Tsinghua University addresses this by conditioning velocity prediction on an utterance-level realization latent variable that is kept explicit rather than integrated out. The realization space is further structured with valence-arousal-dominance (VAD) semantics, giving graded, interpretable control over prosodic attributes at inference time — no reference speech required.
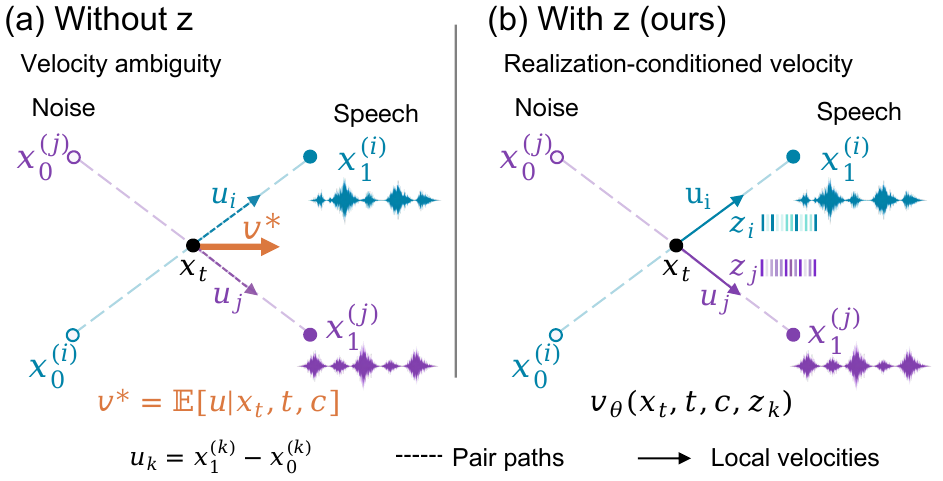
ReaFlow-TTS: Realization-Conditioned Flow Matching for High-Quality and Controllable Speech Synthesis
ReaFlow-TTS introduces a realization-conditioned flow-matching framework that explicitly models speech variation by conditioning velocity prediction on an utterance-level latent variable, rather than marginalizing it away. The approach further imposes valence-arousal-dominance semantics on the realization latent space, enabling direct and graded control over prosodic attributes without requiring reference speech at inference time.
Abstract
In flow-matching text-to-speech (TTS), different speech realizations can induce different target velocities under the same generation conditions. A deterministic velocity field trained with squared error predicts their conditional mean, thereby marginalizing realization-dependent variation. Meanwhile, modeling such variation does not inherently provide a semantically interpretable interface for attribute manipulation. We propose ReaFlow-TTS, a realization-conditioned flow-matching framework that introduces an utterance-level stochastic realization latent and uses it to condition velocity prediction throughout the generation trajectory. We further impose valence-arousal-dominance (VAD) semantics on the realization space, enabling direct and graded attribute manipulation without target speech at inference. Experiments demonstrate improved synthesis quality over a matched full-mask baseline and reproducible latent-induced pitch, energy, and timing tendencies across initial-noise samples, providing behavioral evidence that the latent is used as a reusable realization condition. Subjective evaluation further demonstrates graded VAD manipulation across generation contexts with only modest changes in naturalness.
Trending on Hugging Face

Vidu S2: Real-Time Interactive, Editable, and Spatial Video Generation
Vidu S2 introduces real-time interactive avatar and video editing models that support high-resolution spatial video generation and dynamic reference updates.

Vidu S1: A Real-Time Interactive Video Generation Model
Vidu S1 is a real-time interactive video generation model that supports voice-controlled digital character animation with infinite-length output and high frame rate on consumer hardware.

OmniFlatten: An End-to-end GPT Model for Seamless Voice Conversation
A novel GPT-based model, OmniFlatten, enables real-time natural full-duplex spoken dialogue through a multi-stage post-training technique that integrates speech and text without altering the original model's architecture.

VoiceMem: Streaming Dual-Brain Memory for Real-Time Interaction
VoiceMem introduces a dual-brain streaming memory architecture for speech language models that improves retrieval accuracy, emotional personalization, and real-time efficiency.

Qwen3-TTS Technical Report
The Qwen3-TTS series presents advanced multilingual text-to-speech models with voice cloning and controllable speech generation capabilities, utilizing dual-track LM architecture and specialized speech tokenizers for efficient streaming synthesis.