From Deepfake Defense to End-to-End Waveforms: Speech & Avatar Research, Nov 10
Today's digest spans talking-avatar control, deepfake voice protection, compact multilingual TTS, end-to-end waveform synthesis, flow-matching guidance fixes, beat-adaptive rap synthesis, speech reward modeling, and cascaded spoken-dialogue optimization.
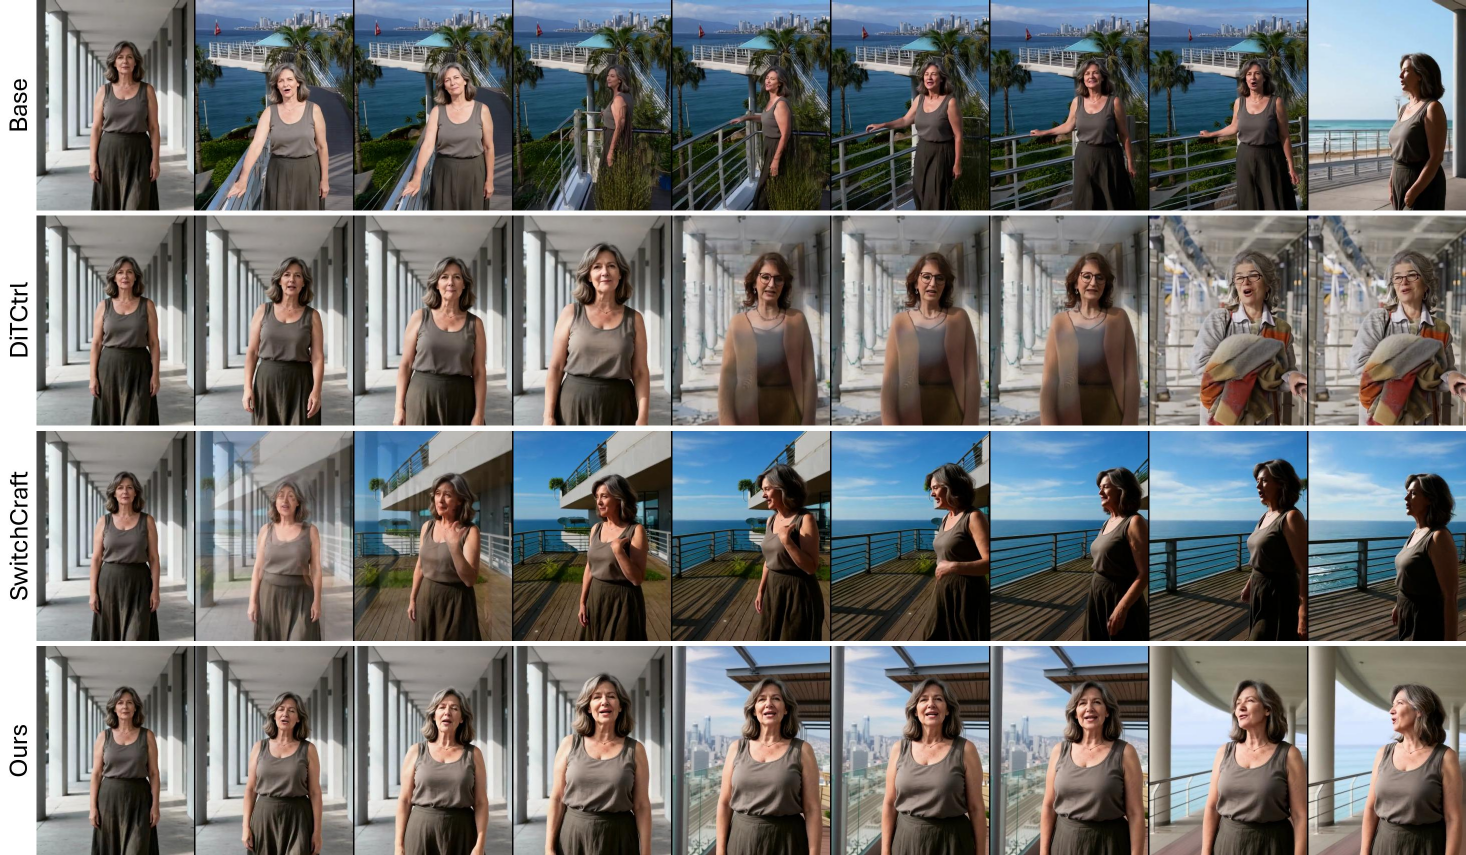
Qualitative comparison on InfiniteTalk. The prompted scene sequence is a covered outdoor walkway, a rooftop terrace, and a beachside promenade. % SceneShifter produces distinct backgrounds while maintaining the subject's appearance across transitions. From The University of Sydney.
Today's papers cover a wide arc of the audio-driven AI stack — from training-free animation control and deepfake voice protection, through compact on-device TTS and truly end-to-end waveform generation, to nuanced reward modeling and cascaded dialogue optimization. There's something for practitioners on every rung of the pipeline.
Talking Avatars & Audio-Driven Animation
Controlling the visual world around a speaker, and defending against those who'd weaponize it.
Audio-driven human animation has matured to the point where the background itself is becoming an expressive parameter. SceneShifter from the University of Sydney tackles the problem of multi-scene temporal control — seamlessly swapping backgrounds at precise timestamps while keeping the foreground subject intact. The key mechanism is attention manipulation inside a diffusion transformer to decouple background and foreground representations, combined with dynamic foreground masking that robustly tracks subjects even under large motion. Crucially, it requires no additional training.
SceneShifter: Training-free Multi-Scene Temporal Control for Audio-driven Human Animation
SceneShifter enables precise multi-scene temporal control in audio-driven human animation by manipulating diffusion transformer attention to decouple background and foreground, allowing seamless background transitions at specific timestamps while preserving subject identity. The training-free approach uses dynamic foreground masking to track subjects under large motion, addressing a key limitation in existing video generation models.
Abstract
Although audio-driven human animation has achieved impressive realism, it still lacks effective Multi-Scene Temporal Control: orchestrating background transitions at precise timestamps while preserving a coherent foreground subject. We show that this challenge stems from the diffusion transformer's self-attention mechanism, and addressing it requires two capabilities: (1) Semantic-Aware Temporal Decoupling, which isolates background attention across scenes while retaining cross-scene foreground attention for subject consistency; and (2) Foreground Motion Localization, which accurately tracks the foreground subject across latent frames, especially under large motion. To address these challenges, we introduce SceneShifter, a training-free framework for precise multi-scene control in audio-driven human animation. SceneShifter guides spatio-temporal self-attention by suppressing cross-scene attention among background tokens while preserving cross-scene attention among foreground tokens. To support this guidance under large motion, SceneShifter extracts dynamic foreground masks from the self-attention layers and heads that best capture subject trajectories. We further introduce SceneShifterBench, a benchmark designed to evaluate scene-timing accuracy, foreground preservation, and visual quality under large motion, multiple subjects. Experiments show that SceneShifter achieves frame-level scene timing, strong subject preservation, and high visual quality, outperforming existing baselines. Code is available at https://github.com/JamesLong199/SceneShifter.
On the defensive side, MUTE (AIM Intelligence) addresses the growing threat of talking-head deepfakes exploiting real audio. Rather than applying generic audio watermarking, MUTE directly targets the audio-visual synchronization dependency that talking-head models rely on — disrupting it at two levels: alignment-level attention disruption and representation-level audio degradation. The result is a protection scheme that holds up against post-processing and adaptive attacks while keeping the audio perceptually clean for legitimate uses.
MUTE: Multi-Level Alignment Uncoupling Against Talking-Head Exploitation for Voice Protection
MUTE protects audio from talking-head deepfakes by disrupting audio-visual alignment through multi-level perturbations: alignment-level attention disruption and representation-level audio degradation. Unlike prior audio protection methods, it directly targets the synchronization dependency of talking-head synthesis, maintaining robustness against post-processing and adaptive attacks while preserving audio quality.
Abstract
Talking-head generation models, which synthesize realistic facial animations from audio, are increasingly vulnerable to misuse in multimodal deepfake scenarios. Protecting such systems remains challenging, as talking-head models fundamentally rely on precise audio-visual alignment, while effective audio protection methods remain largely underexplored. In this work, we propose MUTE, an audio protection framework that uncouples the underlying audio-visual alignment through a multi-level strategy. Specifically, MUTE combines (1) Alignment-level Disruption, which directly perturbs cross-modal attention to disrupt structural alignment, and (2) Representation-level Degradation, which perturbs temporal audio embeddings to degrade their representations. To improve robustness, perturbations are constrained in the STFT domain to high-energy regions, making them resistant to post-processing, denoising, and adaptive attacks. An optional speaker-level objective further mitigates potential bypass via TTS-based resynthesis. Extensive experiments demonstrate that MUTE consistently degrades lip synchronization across both white-box and black-box talking-head models while preserving perceptual audio quality. The proposed method remains effective under real-world transformations and can be combined with image-based approaches to provide stronger multimodal protection. The source code and project page are available at https://github.com/jindl465/MUTE.
TTS & Voice Synthesis
Efficiency, architecture innovation, and nuanced quality control across text-to-speech.
Compact & On-Device Synthesis
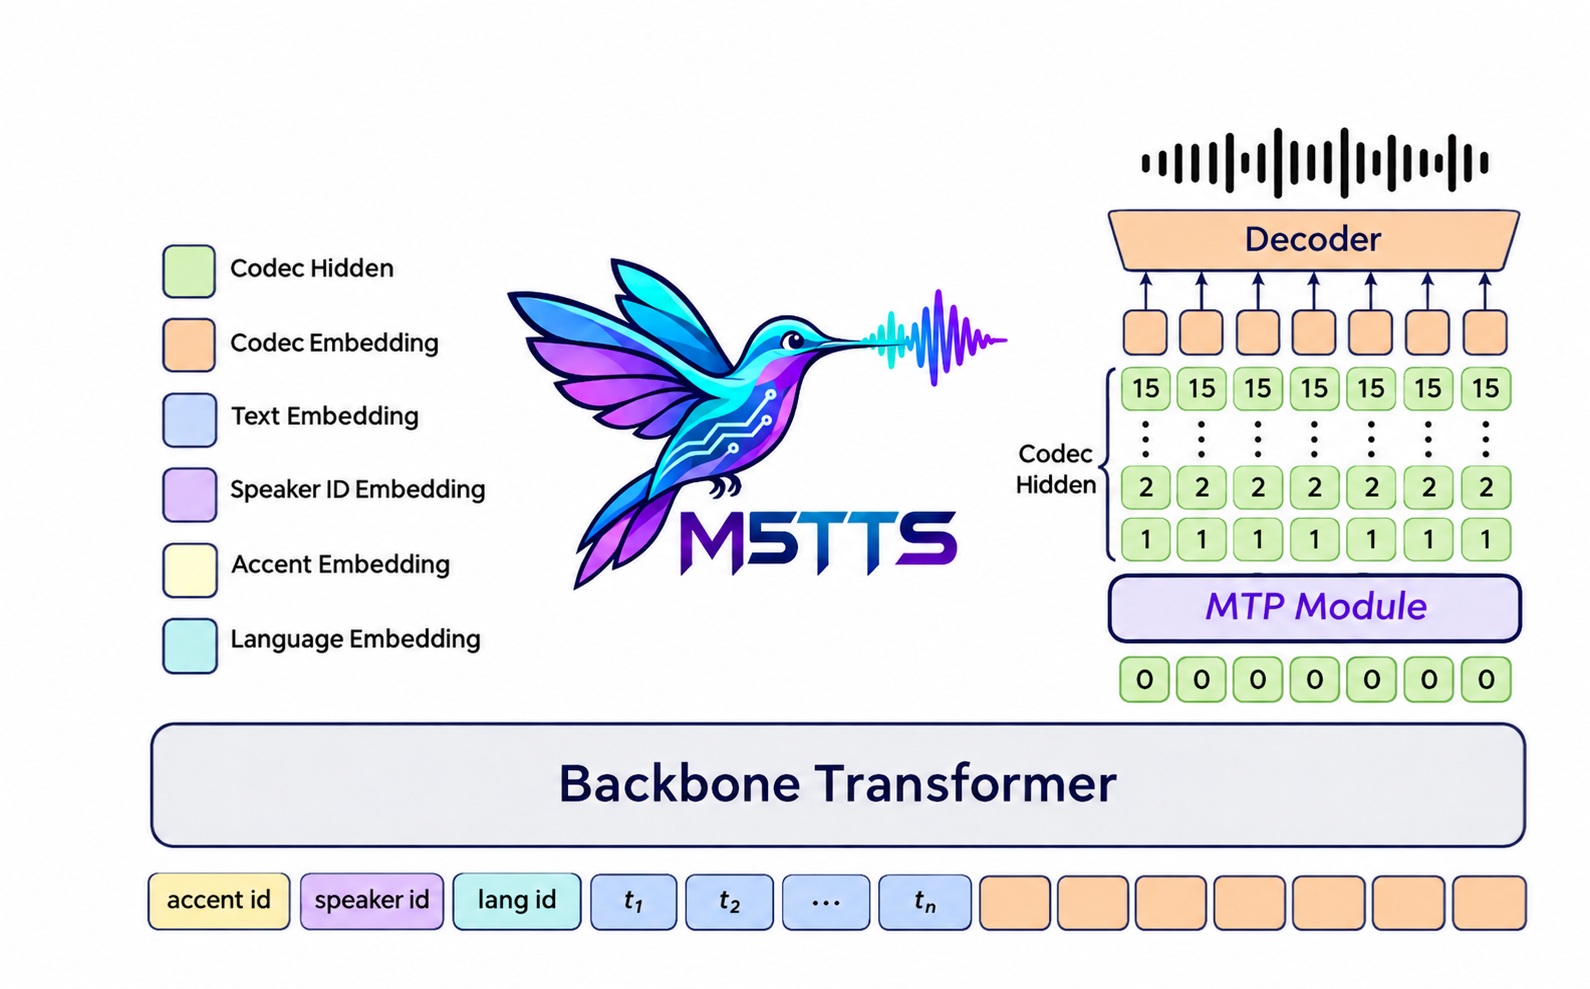
The push for on-device TTS continues. M5-TTS from the WeNet Open Source Community delivers a 50M-parameter system capable of multilingual and Chinese multi-dialect synthesis with zero-shot voice cloning, running efficiently on CPU. The architecture pairs a temporal backbone with multi-token prediction across 16 codebooks, and applies GRPO post-training with character-level and pause-based rewards — achieving competitive quality at roughly half the parameter count of comparable systems.
M5-TTS: A Mini-Scale Multilingual and Multi-Dialect Text-to-Speech Language Model with Multi-Token Prediction
M5-TTS is a compact 50M-parameter text-to-speech system supporting multilingual and Chinese multi-dialect synthesis with zero-shot voice cloning and efficient CPU streaming. It combines a temporal backbone with multi-token prediction over 16 codebooks and uses GRPO post-training with character-level and pause-based rewards, achieving strong performance with half the parameters of comparable systems while maintaining low latency for on-device deployment.
Abstract
We present M5-TTS, a compact text-to-speech system supporting multilingual and Chinese multidialect synthesis, zero-shot voice cloning, speaker-specific multilingual generation, and CPU streaming. Its 50M-parameter language model, excluding the speech codec, combines a temporal backbone with a local multi-token prediction module over 16 codebooks. GRPO post-training combines global speaker-similarity and pause feedback with a token-level CER process advantage. Character-level error comparisons provide local feedback, with negative credit propagated backward within a clause and projected onto audio-token positions. M5-TTS achieves 1.37% CER on Seed-ZH and 2.91% WER on Seed-EN, corresponding to relative error reductions of 62.2% and 35.3% over MOSS-TTS-Nano with half the language-model parameters. It also achieves lower content error rates in five of six evaluated MiniMax languages, while difficult Chinese inputs remain a limitation. On four Intel Xeon Gold 6530 cores, it achieves a real-time factor of 0.653 and a warm first-chunk latency of 225ms. A 10-listener evaluation gives M5-TTS higher speaker-similarity and intelligibility ratings than MOSS-TTS-Nano, with a lower naturalness rating. We will release training, post-training, and inference code, together with voice-cloning and speaker-specific checkpoints, to support reproducible research on compact speech generation for on-device voice interaction.
End-to-End Waveform Generation
Most TTS pipelines still rely on a chain of specialized modules — acoustic models, neural codecs, vocoders. WaveGen (Ajou University) takes a different stance: a fully end-to-end diffusion-based framework that generates raw waveforms directly from text in a single model, with no intermediate representations, external alignment modules, or self-supervised pretrained dependencies. The enabling technique is Spectral Forcing, which jointly learns internal spectral and waveform trajectories, keeping the model coherent across both domains without decomposing the problem.
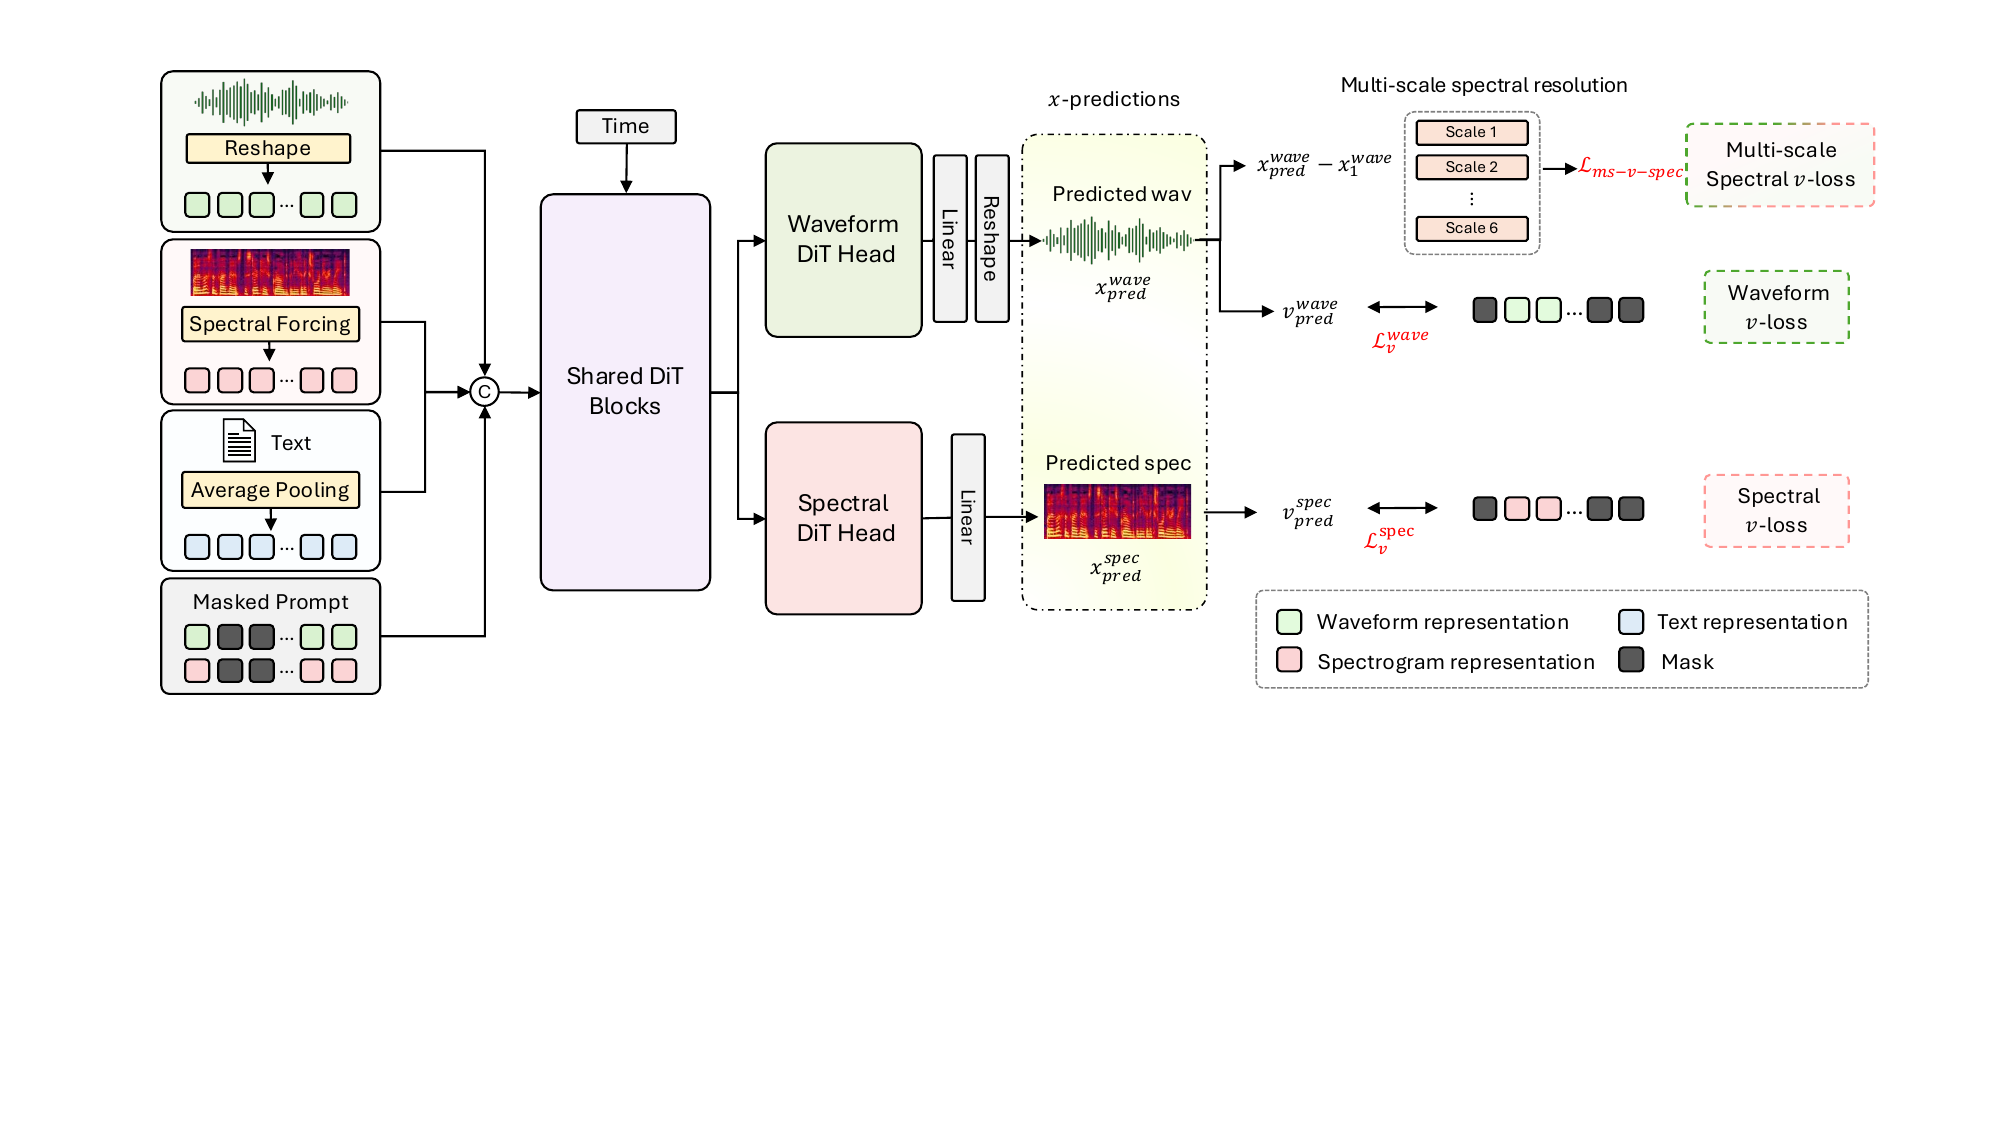
WaveGen: Truly End-to-End Waveform Generation via Internal Spectral Trajectory Learning
WaveGen is a fully end-to-end diffusion-based text-to-waveform framework that generates speech directly from text within a single model, eliminating separate intermediate representations like neural codecs and vocoders. Using Spectral Forcing to jointly learn internal spectral and waveform trajectories, it enables truly unified synthesis without external alignment modules or dependence on self-supervised pretrained models.
Abstract
This work proposes WaveGen, a fully end-to-end diffusion-based text-to-waveform framework based on Spectral Forcing, which jointly learns an internal spectral trajectory and the target waveform trajectory within a single model, enabling direct end-to-end text-to-waveform generation. Unlike recent TTS pipelines, WaveGen does not rely on separately trained or externally decoded intermediate representations, such as neural audio codecs, Mel-spectrogram vocoders, or VAE-based latent models. In addition, WaveGen performs internal text-speech alignment within a single model, eliminating the need for external alignment modules such as duration predictors. To preserve a truly end-to-end formulation, our framework further avoids dependence on self-supervised representations, such as BERT-based text embeddings and Wav2Vec 2.0-based semantic representations, as well as semantic distillation methods for training optimization. To achieve this, we carefully design Spectral Forcing, a model architecture with disentangled diffusion heads, and a training objective based on a multi-scale spectral $v$-loss. We further validate the scalability of end-to-end TTS models by scaling the model size from 0.1B to 0.6B parameters. Using a single architecture, open-source data, and one-stage training, without external modules such as duration predictor or REPA, WaveGen demonstrates fully end-to-end waveform generation achieving state-of-the-art performance on the Emilia training dataset. In particular, WaveGen achieves a WER of 1.47 and a SIM of 0.75 on the Seed-en benchmark. Source code and checkpoints are available at https://github.com/sh-lee-prml/WaveGen
Flow-Matching Guidance Fixes
Few-step flow-matching TTS is fast, but there's a hidden cost. Researchers at Korea University show that applying classifier-free guidance on the very first denoising step — where the input is pure noise — shifts every trajectory by nearly the same vector, systematically collapsing speaker diversity. Their proposed FSU and FSU-Mid samplers simply skip guidance on that first step (no retraining required), recovering 77–91% of the lost speaker similarity while keeping latency at 2–3 network evaluations.
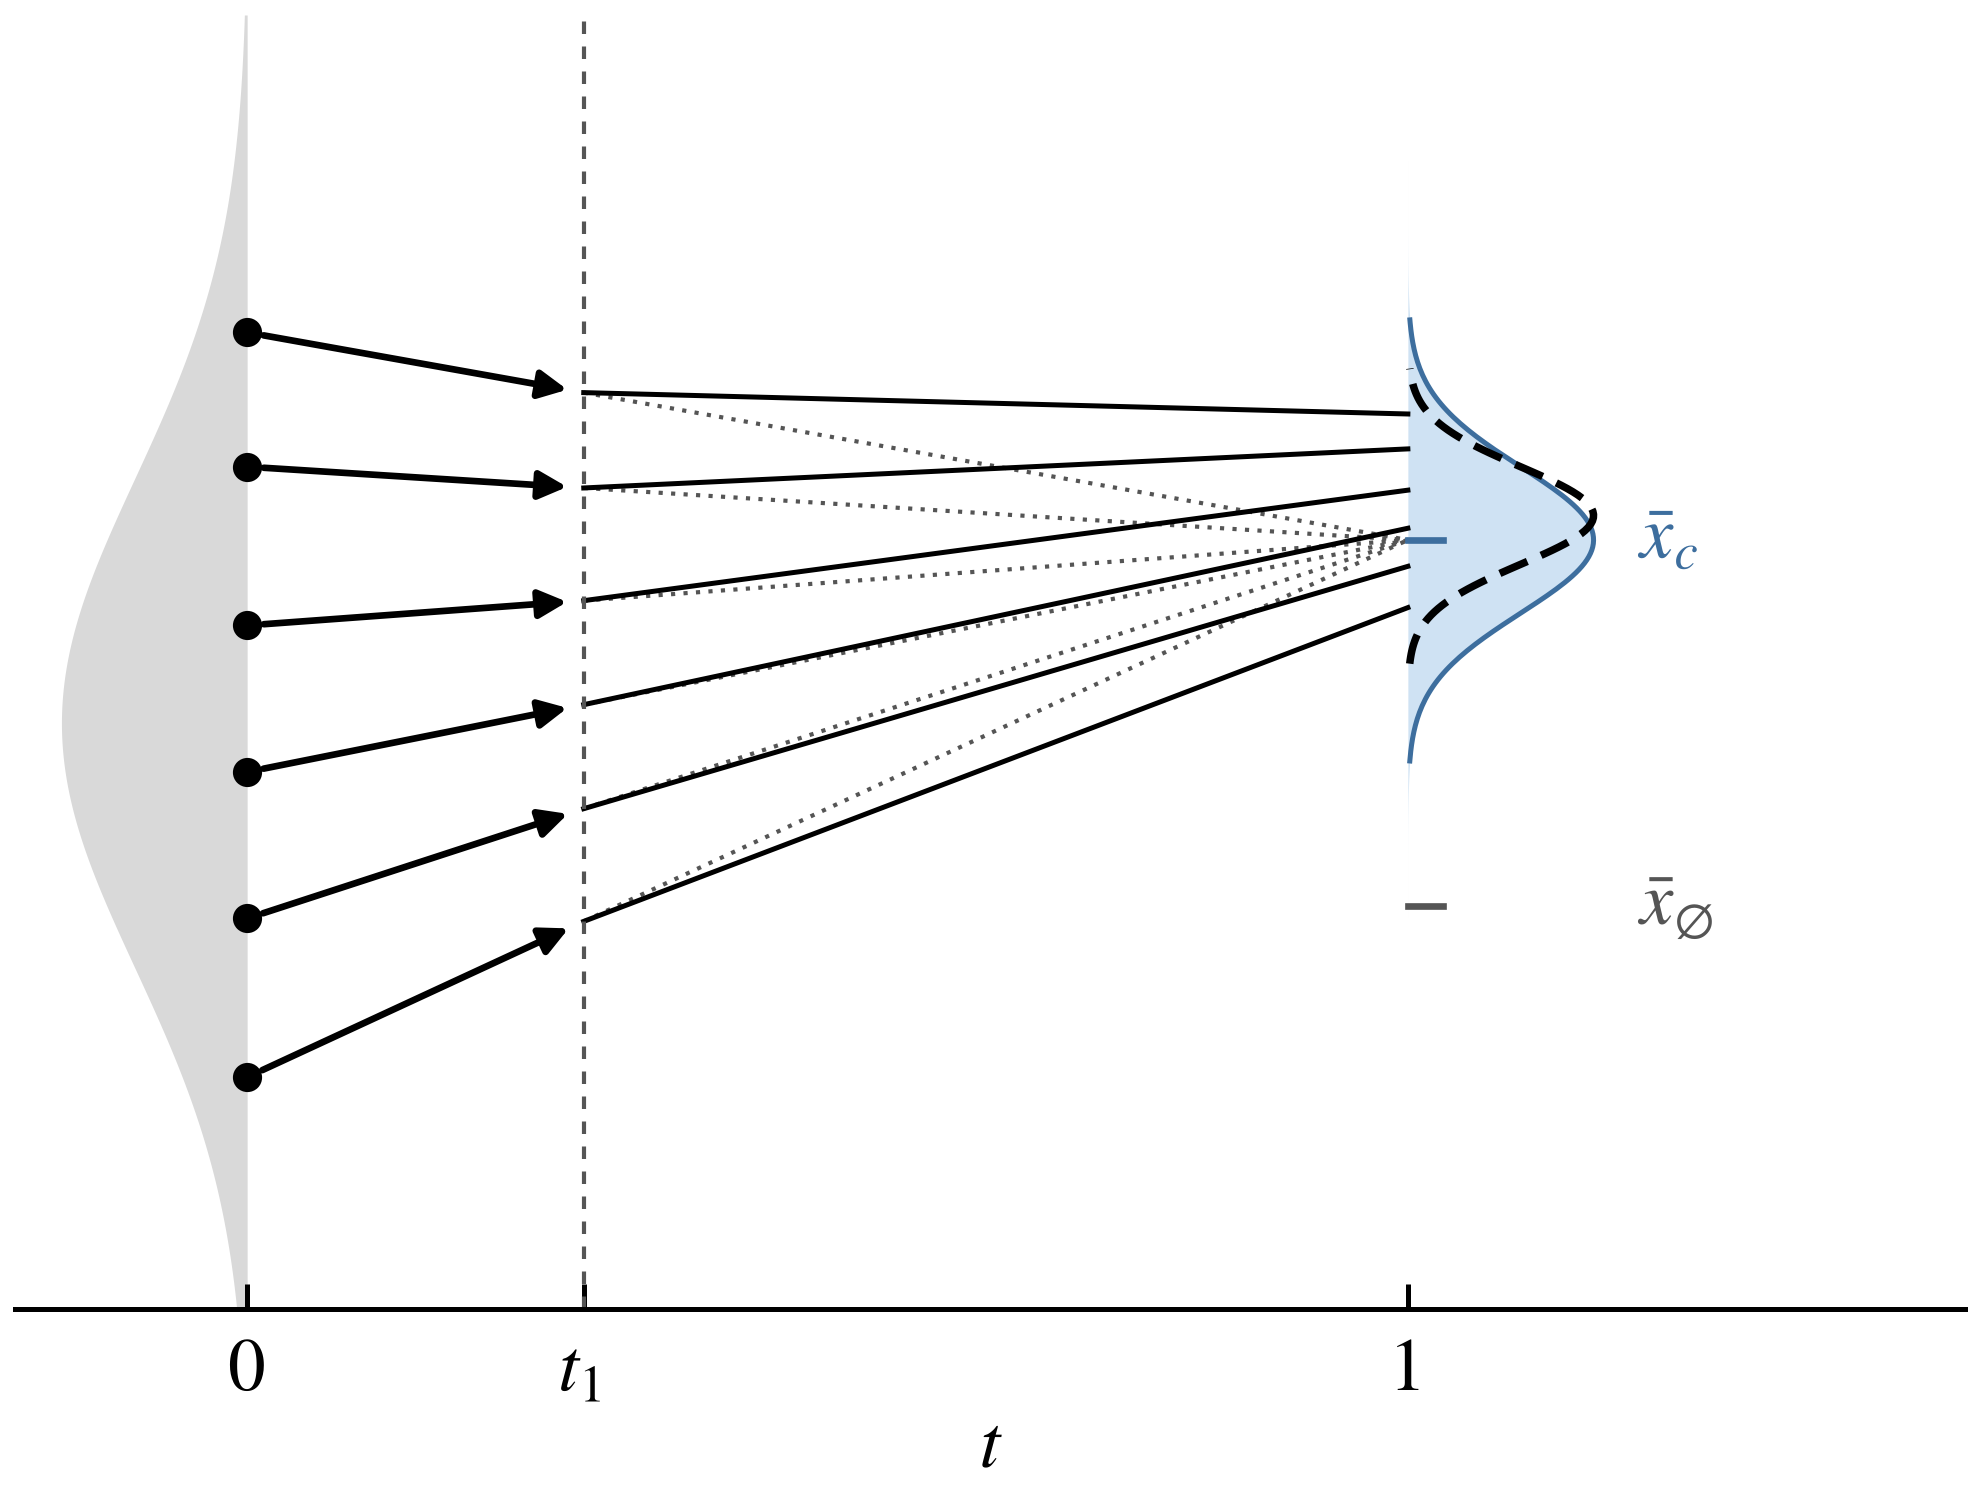
Guidance at Pure Noise Erodes Speaker Similarity in Few-Step Token-Conditioned Flow-Matching TTS
This paper identifies why few-step flow-matching TTS loses speaker similarity: classifier-free guidance on the first step shifts every trajectory by nearly the same vector, compounding the error. The authors propose FSU and FSU-Mid—training-free samplers that skip guidance on the first step to recover 77–91% of similarity loss while maintaining real-time latency with only 2–3 network evaluations, matching or exceeding published guidance rules.
Abstract
Text-to-speech systems built from a language model and a flow-matching mel decoder now run the decoder with two to four Euler steps instead of the official ten or more. At two steps the word error rate (WER) is unchanged, but speaker similarity (SIM) drops by one to six points. This paper shows that most of this loss comes from classifier-free guidance on the first step. At pure noise the network can only return the conditional mean, so guidance shifts every trajectory by nearly the same vector. Later steps do not remove this shift, and its size grows with the length of the first step, so it is negligible with ten or more steps and accounts for most of the loss with two. Two training-free samplers are derived from this analysis. First-step unguided sampling (FSU) leaves the first step unguided and recovers $84$--$91\%$ of the two-step SIM loss on CosyVoice~2/3 with no significant WER increase. FSU-Mid replaces the two Euler steps by one midpoint step with an unguided first evaluation, recovers $77$--$85\%$ on IndexTTS-2 and matches the ten-step teacher on CosyVoice~2 and GLM-TTS. Both use three network function evaluations, one fewer than the official two-step sampler, and FSU-Mid gives the highest mean recovery among eight published guidance rules re-run at two steps on four decoders.
Beat-Adaptive Rap Synthesis
Rap synthesis presents unique challenges: non-standard orthography, tight rhythmic constraints, and the need to decouple vocal tempo from underlying beat timing. BARS (ISMIR 2026) is a non-autoregressive flow-matching model that handles all three. It combines beat-adaptive generation, a specialized text encoder for rap's lexicon, and Asymmetric Scaled RoPE for stable lyric-audio alignment — achieving high lyric fidelity and natural flow across styles without locking vocal tempo to the beat grid.
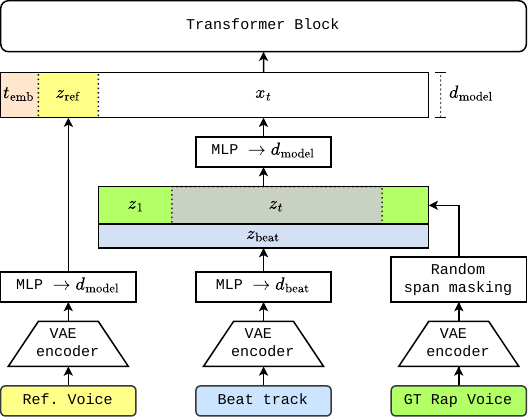
BARS: Beat-Adaptive Rap Synthesis via Flow Matching
BARS presents a non-autoregressive rap synthesis model that decouples vocal tempo from beat timing, enabling flexible-length generation with independent tempo control while maintaining rhythmic coherence. By combining beat-adaptive generation, specialized text encoding for rap's non-standard orthography, and Asymmetric Scaled RoPE for stable lyric-audio alignment, the model achieves high lyric fidelity and natural rap flow across diverse styles.
Abstract
We present BARS (Beat-Adaptive Rap Synthesis), a non-autoregressive rapping voice generation model based on Flow Matching, conditioned on a beat track (instrumental backing), lyrics, and a short reference voice for zero-shot timbre control. Unlike prior autoregressive rap synthesis, where rap pace and output duration are strictly determined by the beat, BARS enables independent control over the rap tempo, allowing flexible-length generation without explicit duration prediction or phoneme-level alignment. We encode lyrics using a pretrained ByT5 encoder with a lightweight Transformer adapter trained jointly with the model, without relying on speech-pretrained text encoders, enabling natural handling of non-standard orthography (e.g., slang, abbreviations) and numerals common in rap lyrics. To address alignment instabilities, such as token skipping or repetition, under strong beat conditioning, we propose Asymmetric Scaled RoPE for cross-attention, which introduces a positional structure to facilitate sequential lyric-audio alignment learning. Furthermore, the model supports partial re-generation via span masking, enabling lyric-level editing while preserving the surrounding vocal style. Experiments demonstrate that the proposed model achieves high lyric fidelity, natural rap flow that is rhythmically coherent with the beat, and robust tempo control across a wide range of rapping styles and speeds.
Speech Reward Modeling
Training speech synthesis with reinforcement learning requires reliable reward signals, but most reward models operate on implicit utterance-level preferences that offer little interpretability or supervision granularity. REAL (Zhejiang University) changes this by grounding reward predictions in structured, evidence-linked explanations — explicitly connecting specific audio spans to perceptual phenomena and quality dimensions before aggregating into an overall lifelikeness score. This local-to-global supervision chain is a meaningful step toward transparent, debuggable speech quality models.
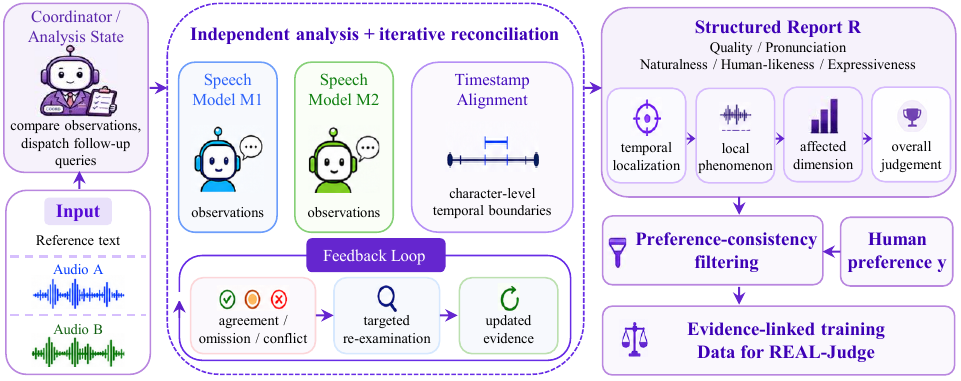
REAL: Reward Modeling through Evidence-Linked Analysis of Lifelikeness in Generated Speech
REAL introduces a framework for training speech reward models that ground preference predictions in structured, evidence-linked explanations—linking specific audio spans to perceptual phenomena and quality dimensions. This explicit supervision approach uniquely connects local acoustic observations to overall lifelikeness judgments, moving beyond implicit utterance-level preferences in prior reward modeling work.
Abstract
As modern text-to-speech systems become increasingly intelligible and natural, evaluation is shifting from detecting gross synthesis failures to identifying subtle departures from lifelike human delivery. Because large-scale listening tests are costly and slow, speech reward models can serve as scalable automatic judges for comparing generated utterances, curating data, and supporting iterative TTS development. Existing speech reward models can predict scores or pairwise preferences and may generate natural-language rationales, but their supervision is typically defined at the utterance or pair level. The connection between local acoustic phenomena and the final preference therefore remains implicit. We introduce REAL, a framework for Reward modeling through Evidence-linked Analysis of Lifelikeness in generated speech. Its central idea is to supervise not only the final pairwise preference but also a structured account of its supporting observations, linking local audio spans to perceptual phenomena, affected dimensions, and the overall judgment. Specifically, REAL-Jury constructs these evidence-linked reports through timestamp alignment, multi-model analysis, and dispute-oriented deliberation. REAL-Judge learns to generate them from paired audio inputs. REAL-Eval assesses preference prediction in two tiers, from salient perceptual differences to subtle distinctions among strong TTS systems. Instantiated with MiMo-Audio, REAL-Judge improves pairwise preference accuracy over its backbone by 16.01 and 11.41 percentage points on the two tiers, respectively, and outperforms the open-source speech reward models SpeechJudge and UniSRM on both tiers.
Spoken Dialogue & Voice Agents
Optimizing the full cascaded pipeline for real spoken interaction.
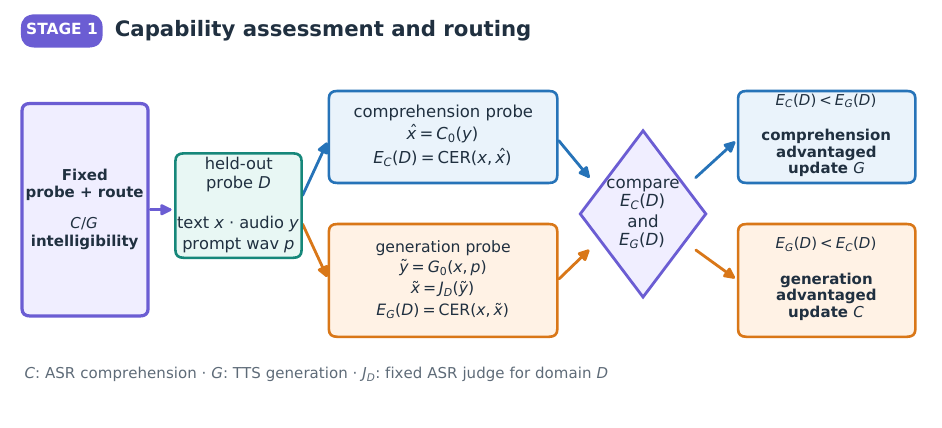
Cascaded spoken-dialogue systems (ASR → LLM → TTS, etc.) are hard to optimize end-to-end because supervision signals don't flow cleanly across module boundaries. The team at Shanghai Jiao Tong University proposes a capability-guided iterative optimization framework that exploits the reciprocal speech-content interfaces between modules. A shared intelligibility probe assesses each module's relative strength, then adaptively routes acoustic or content-only data through the stronger teacher — enabling cross-module supervision without hardcoding which direction the signal travels. The framework is domain-specific and iterative, making it practical for real deployment scenarios.
Capability-Guided Iterative Online Optimization of Cascaded Spoken-Dialogue Modules
This paper proposes a capability-guided iterative optimization framework for cascaded spoken-dialogue systems that exploits reciprocal speech-content interfaces to enable cross-module supervision. The key innovation is a two-stage pipeline that assesses module capability through a shared intelligibility probe and adaptively routes either acoustic or content-only data through the stronger teacher, enabling domain-specific optimization without hardcoding supervision direction.
Abstract
Cascaded spoken dialogue systems comprise perception-and-comprehension, decision-making, and response-generation modules. We study iterative optimization of the first and last modules. Their reciprocal speech-content interfaces enable one-sided data to provide cross-module supervision: acoustic observations, such as waveforms or feature sequences, can be pseudo-labeled to train generation, whereas content-only samples can be rendered into speech to train comprehension. Because the reliable teacher-student direction varies across domains, we propose a two-stage, capability-guided pipeline for iterative online optimization. Stage 1 compares both modules through a shared intelligibility probe and obtains a domain-wise capability prior. Stage 2 activates the compatible one-sided-data route, constructs and filters supervision with the current teacher, updates the selected student, and refreshes the relevant checkpoints across cycles. We instantiate comprehension with Whisper large-v3 and generation with CosyVoice2. After only 200 steps for Whisper and 600 for CosyVoice2 of our iterative online optimization, we observe that, on the Chinese MAGICDATA-RAMC dataset, Whisper reduces CER from 14.18% to 10.77%, while CosyVoice2 reduces it from 4.78% to 4.04%. On the Japanese Common Voice dataset, Whisper reduces CER from 15.23% to 15.10%, while CosyVoice2 reduces it from 14.85% to 11.18%. These results demonstrate the feasibility of capability-guided iterative optimization of complementary spoken-dialogue modules.
Trending on Hugging Face

OmniFlatten: An End-to-end GPT Model for Seamless Voice Conversation
A novel GPT-based model, OmniFlatten, enables real-time natural full-duplex spoken dialogue through a multi-stage post-training technique that integrates speech and text without altering the original model's architecture.

VibeVoice Technical Report
VibeVoice synthesizes long-form multi-speaker speech using next-token diffusion and a highly efficient continuous speech tokenizer, achieving superior performance and fidelity.

Qwen3-TTS Technical Report
The Qwen3-TTS series presents advanced multilingual text-to-speech models with voice cloning and controllable speech generation capabilities, utilizing dual-track LM architecture and specialized speech tokenizers for efficient streaming synthesis.

IndexTTS: An Industrial-Level Controllable and Efficient Zero-Shot Text-To-Speech System
IndexTTS, an enhanced text-to-speech system combining XTTS and Tortoise models, offers improved naturalness, enhanced voice cloning, and controllable usage through hybrid character-pinyin modeling and optimized vector quantization.

Fish Audio S2 Technical Report
Fish Audio S2 is an open-source text-to-speech system with multi-speaker capabilities, multi-turn generation, and instruction-following control through natural-language descriptions, utilizing a multi-stage training approach and production-ready inference engine.